Skip to content
CloudSyntrixAI & HPC Buildouts

GPU & Fabric

From racked equipment to a validated cluster.

Bring GPU systems, high-performance networking and storage into one coordinated deployment, then test it against agreed criteria.
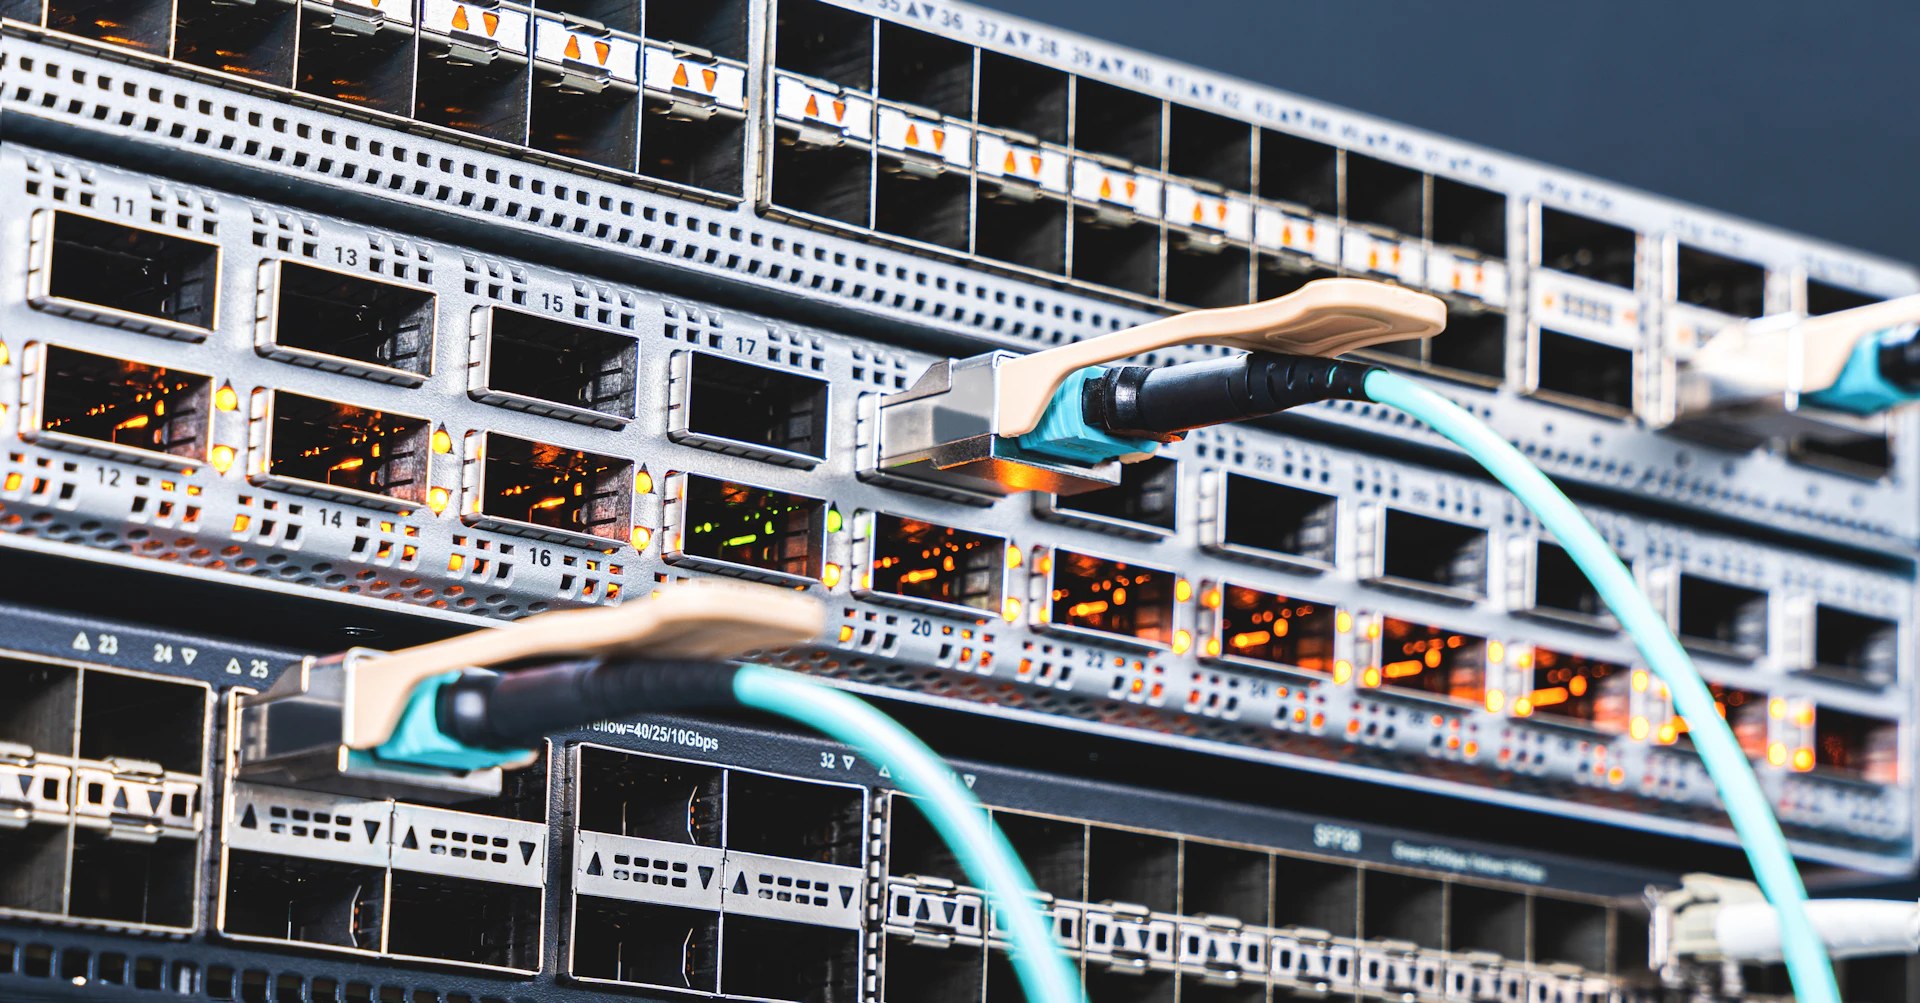
Network switches connected with teal fiber patch cables

In your program

What you could hand to CloudSyntrix

  • GPU system installation, firmware baselining and OS imaging
  • InfiniBand and Ethernet fabric deployment and validation
  • Storage integration and cluster configuration
  • Acceptance testing against agreed criteria

To agree per project: Which acceptance criteria apply, and who operates the cluster afterward.

Where this sits in a buildout

A GPU deployment as eight work packages in an illustrative order01Site readiness02Power & cooling03Racks04Cabling05GPU systems06Fabric & storage07Validation08HandoffIllustrative order. The real sequence and interfaces are set per project.
  1. 01 Site readiness
  2. 02 Power & cooling
  3. 03 Racks
  4. 04 Cabling
  5. 05 GPU systems
  6. 06 Fabric & storage
  7. 07 Validation
  8. 08 Handoff
The highlighted steps are covered on this page.

The integration work

01

GPU systems

GPU system installation, BIOS and firmware baselining, and OS imaging.

Gate Systems are on an agreed firmware baseline and image.

02

Fabric and storage

InfiniBand and Ethernet fabric deployment and validation, with storage integration and cluster configuration.

Gate Fabric and storage are configured and tested against the agreed design.

03

Validation and acceptance

Benchmarking and acceptance testing against criteria agreed for the project (for example NCCL/RCCL and HPL). No published benchmark score is claimed.

Gate Acceptance criteria agreed up front are met and recorded.

How the pieces connect

GPU systems, a high-performance fabric and storage are installed, configured and tested together. The diagram is illustrative: the actual design, technologies and rates are agreed per project.

Illustrative connection of compute nodes, leaf and spine switches and storageGPU nodeGPU nodeGPU nodeGPU nodeGPU nodeGPU nodeLeaf switchLeaf switchLeaf switchSpine switchSpine switchStorageoften its own fabricIllustrative only. Not a design for any project: topology, link rates and technology are agreed per project.A GPU server usually has several network ports, each on a different leaf. One is shown for clarity.
  1. GPU nodesCompute servers carrying the GPUs
  2. Leaf and spine switchesLeaf switches connect the nodes; spine switches connect the leaves to each other
  3. StorageShared data storage, often on its own fabric

Supporting breadth

Orchestration
Slurm, Kubernetes and the GPU Operator, Base Command Manager, Run:ai, OpenShift AI, Ansible
Storage
DDN, VAST, Pure, NetApp, WEKA; Lustre and GPFS
Platforms
NVIDIA (HGX/DGX, BasePOD/SuperPOD), AMD (Instinct, ROCm), and OEM systems from Dell, HPE, Supermicro, Lenovo and Cisco
Security and operations
Kubernetes hardening, identity and RBAC, segmentation, monitoring (DCGM, Prometheus, Grafana), ServiceNow ITSM integration, tenant onboarding
AI and cloud
MLOps and model serving, hybrid on-prem and Azure/AWS connectivity, and enterprise AI and data work as a secondary capability

These are offered scope drawn from CSTX service materials. They are not completed-deployment claims, published performance, certifications or partner tiers.
Fiber plugged into a dense patch panel

Ask the assistant

Still have a question?

The assistant answers from approved content and says plainly what it cannot claim.